The debate between “autonomous” and “assisted” AI agents is usually framed as a false choice: either you buy a shallow no-code toy that “runs itself” but tops out the moment you need real control, or you rebuild the substrate in raw code — orchestration, retries, state, audit trails — before you can do anything interesting. If you’re an engineer or technical founder, you’ve felt the ceiling of the first option and the tedium of the second.
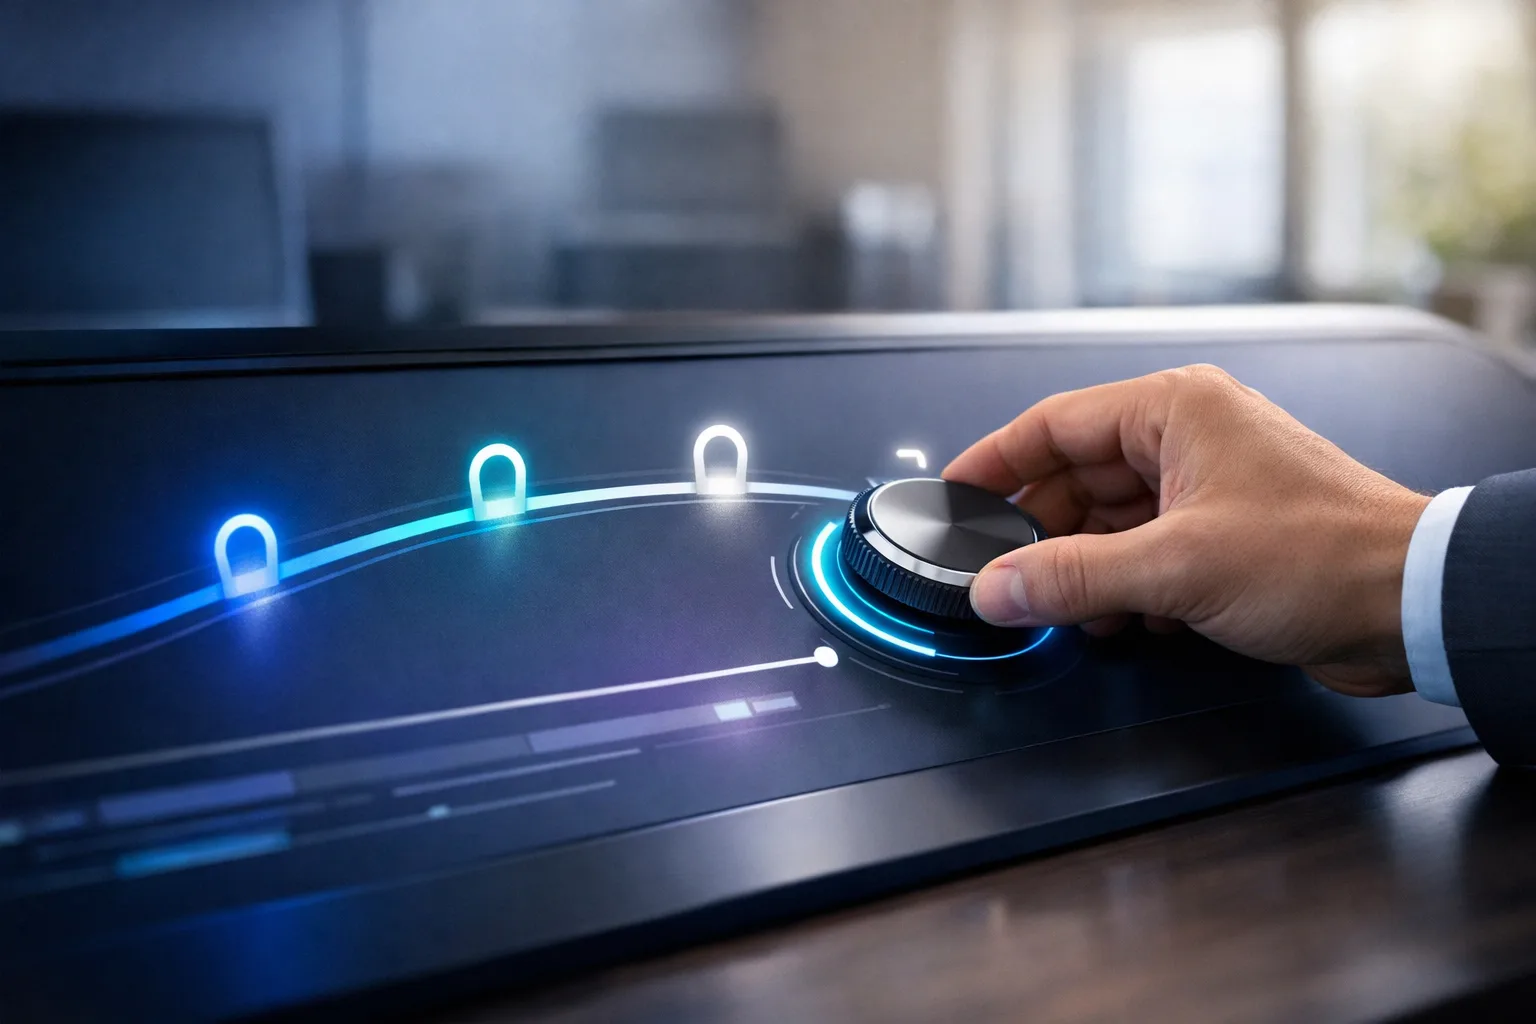
The actual decision isn’t “how much autonomy should my agent have?” It’s a control-surface and failure-mode question: where does a human sit in the loop, what happens when a step goes wrong, and how much blast radius are you willing to accept per decision. Autonomy isn’t a switch. It’s a dial you set per node, per action, per dollar of consequence.
TL;DR: Autonomous and assisted agents differ in decision authority, failure blast-radius, and checkpoint cadence — not in raw capability. The right architecture is a per-action autonomy dial: deterministic steps stay automated, high-consequence steps get approval gates, and the spectrum between them is an engineering decision you own.
What’s the actual difference between autonomous and assisted AI agents?
Autonomous agents own the decision; assisted agents propose it. An autonomous agent selects tools, executes actions, and commits side effects without a human in the critical path. An assisted agent produces a recommendation — a draft, a plan, an approval request — and a human is the one who commits.
But that binary collapses the moment you look at a real system. Autonomy lives on a spectrum, and most production deployments are neither fully autonomous nor fully assisted. They’re selectively autonomous: the same loop runs hands-off for low-stakes steps and pauses at an approval gate for anything consequential. The difference that actually matters is where you place the checkpoint, not whether you have one.
| Dimension | Autonomous | Assisted |
|---|---|---|
| Decision authority | Agent commits side effects | Human approves before commit |
| Failure blast-radius | Errors propagate until a guardrail catches them | Errors surface at the gate, before commit |
| Checkpoint cadence | Rare — end of run or threshold breach | Per high-stakes action |
| Best fit | High-volume, reversible, low-stakes steps | Irreversible, regulated, or high-value steps |
The autonomy spectrum, not the autonomy switch
Think of autonomy as a dial with at least four positions, each with a different failure mode:
-
Human-in-the-loop (HITL). The agent pauses before every consequential action and waits for approval. Highest control, lowest throughput. You’re paying a human’s latency on every step.
-
Human-on-the-loop (HOTL). The agent runs autonomously while a human monitors, intervening only when a threshold is crossed — confidence drops, cost spikes, or an anomaly fires. You get speed with a tripwire instead of a gate.
-
Approval-gated autonomy. The agent executes autonomously except at specific, pre-declared nodes — a payment above a limit, a write to production, a message to a customer. This is the workhorse pattern: you list the irreversible actions, gate those, and let everything else run.
-
Full autonomy. No human in the critical path at all. Only defensible when the action is cheap, reversible, and bounded — and even then, you want an audit trail you can replay.
The engineering skill isn’t picking a position. It’s deciding which actions deserve which position, and making that mapping explicit rather than discovering it after the first bad commit.
Why the failure mode matters more than the label
The word “autonomous” tells you nothing about whether a system is safe to deploy. Two agents can both be called “autonomous” and have completely different risk profiles, because risk is a function of three things:
- Reversibility. A draft email is reversible; a wire transfer is not. Reversible actions tolerate autonomy; irreversible ones demand a gate.
- Consequence magnitude. Reading from a database is cheap; deleting records is not. Consequence, not “complexity,” is what should drive your checkpoint placement.
- Observability. If you can’t see what the agent did and why, you can’t run it autonomously no matter how confident the model is. An agent with a replayable audit trail can be riskier safely; one without it can’t be trusted at any autonomy level.
This is why most serious agent frameworks converge on the same pattern: deterministic steps stay automated, high-consequence steps get approval gates, and a human sits on the loop for everything in between. The ones that ship “full autonomy” as a selling point are usually shipping it for low-stakes domains — or they’re papering over the failure modes you’ll inherit later.
Where raw code wins — and where it doesn’t
Let me be direct about the trade-off, because pretending the DIY path is always wrong insults your time.
Raw code wins when you need fine-grained control over the loop itself: custom retry semantics, bespoke state machines, a specific checkpoint pattern that no framework exposes, or determinism guarantees you can’t get from a generic runtime. If the loop is your product, hand-roll it. You’ll get exactly the control surface you want and you’ll own every failure mode. If you’re still deciding between building in code or leaning on a visual platform, the no-code vs code decision framework walks through that same trade-off in more depth.
Raw code costs you when the plumbing isn’t your differentiator. Orchestration, state persistence, retries, approval gates, audit trails, replay — none of this is intellectually hard, but it’s all tedious, and it’s all code you now maintain forever. Rebuilding substrate that a mature runtime already ships is where the false choice bites: you’re not choosing “control vs. no control,” you’re choosing “control plus maintenance burden” over “control minus plumbing.”
The honest test is whether the plumbing is load-bearing for your product or just table stakes. If it’s table stakes, a platform that gives you the dials — per-action autonomy, approval gates, audit trails — without making you rebuild them is strictly the better trade. Concede the path where raw code genuinely wins; don’t rebuild plumbing as a point of pride.
How do I get depth and control without rebuilding the plumbing?
This is the question underneath the “autonomous vs. assisted” framing, and it deserves a straight answer. If you want to own the skill — to understand agent loops, tool-calling, and human-in-the-loop patterns at the substrate level — then build it yourself. This site exists to teach you exactly that, and hand-rolling is the best way to internalize the failure modes. That path is never the wrong answer when the learning is the point.
But if what you want is the outcome — production-grade AI employees with per-action autonomy, approval gates, and a real audit trail — without rebuilding the plumbing you already understand, there’s a different door. On our own EmployAIQ, the control surface this article describes — approval gates, human-in-the-loop supervision, replayable audit history — is a setting on the employee, not a workflow you assemble and maintain. Full disclosure: we build it. It’s the wrong choice if your goal today is to learn how agents work under the hood; it’s the right one if you’d rather design the role and let the platform own the substrate.
How to choose: a decision framework
Instead of “autonomous vs. assisted,” run every consequential action through four questions:
- Is it reversible? If yes, lean autonomous. If no, gate it.
- What’s the consequence magnitude? Price the worst-case failure. If the number is material, a human approves it.
- Can I observe and replay it? No audit trail, no autonomy — regardless of reversibility.
- What’s the checkpoint cadence worth? Every gate costs latency and attention. Gate only the actions where the cost of a mistake exceeds the cost of a human’s time.
The output isn’t a single architecture decision. It’s a map — action type to autonomy level — that you can express as config rather than bury in code. That’s the difference between a system you trust and one you’re crossing your fingers on.
The autonomy dial maps directly onto which platform you reach for. If you’re weighing visual builders, our Dify vs n8n comparison breaks down where each gives you real control versus shallow defaults, and the n8n vs Make.com comparison covers the same question for automation-first tooling. For a broader sweep across the orchestration landscape — including where full frameworks like LangChain and CrewAI fit versus a visual runtime — see the LangChain vs CrewAI vs n8n comparison. And if you’re trying to place agents against the older automation tools your team already runs, the AI agents vs RPA breakdown clarifies where deterministic scripts end and agentic autonomy begins.
The bottom line
Autonomous vs. assisted isn’t a choice you make once at the top of a project. It’s a per-action engineering decision, driven by reversibility, consequence, and observability — not by a label on a product page. The teams that get this right don’t debate “how autonomous should the agent be.” They ask “which actions deserve a gate, and which can run hands-off,” and they make that mapping explicit, observable, and replayable.
Where raw code is the right answer — when the loop itself is your product — hand-roll it and own every failure mode. But if the plumbing is table stakes and the dials are what you actually need, the false choice is the thing to reject: you shouldn’t have to rebuild the substrate to get the control surface.
Want to design AI employee roles from scratch rather than deploy templates? The AI Agent Architects runs as a small five-week cohort, and the waitlist hears every enrolment date first: Join the AI Agent Architects waitlist
About the Author
Anthony Odole is a former IBM Senior Managing Consultant, where he served as Enterprise Architect on Fortune 500 engagements, and the founder of AIToken Labs. He helps business owners cut through AI hype by focusing on practical systems that solve real operational problems.
His flagship platform, EmployAIQ, is an AI Workforce platform that enables businesses to design, train, and deploy AI Employees — AI agents that function as digital workforce members — that perform real work without adding headcount.